Skip to content
ratliff.ioSmall Business CTO

Current recommendations

Local MoE Flash models — Halo, Spark & Mac Studio

128GB RAM Solutions: Qwen3.8-Flash-Next on Single AMD Ryzen AI Halo, Single NVDA DGX Spark, or Single Mac Studio (M3 Ultra, M5 Ultra 128/256).
Large RAM Solutions: GLM 5.3 Flash or DeepSeek v4.1 Flash on Dual Sparks, or a Single Mac Studio 256/512. Decode charts are hardware; quality charts compare each local model to Claude Opus 4.8 and GPT-5.6 Sol.

Section 1 · Qwen3.8-Flash-Next

Single Desktop Machine

Independent single-machine hosts. Mac Studio on MLX 4-bit measurements where published.

1A · One Halo · decode

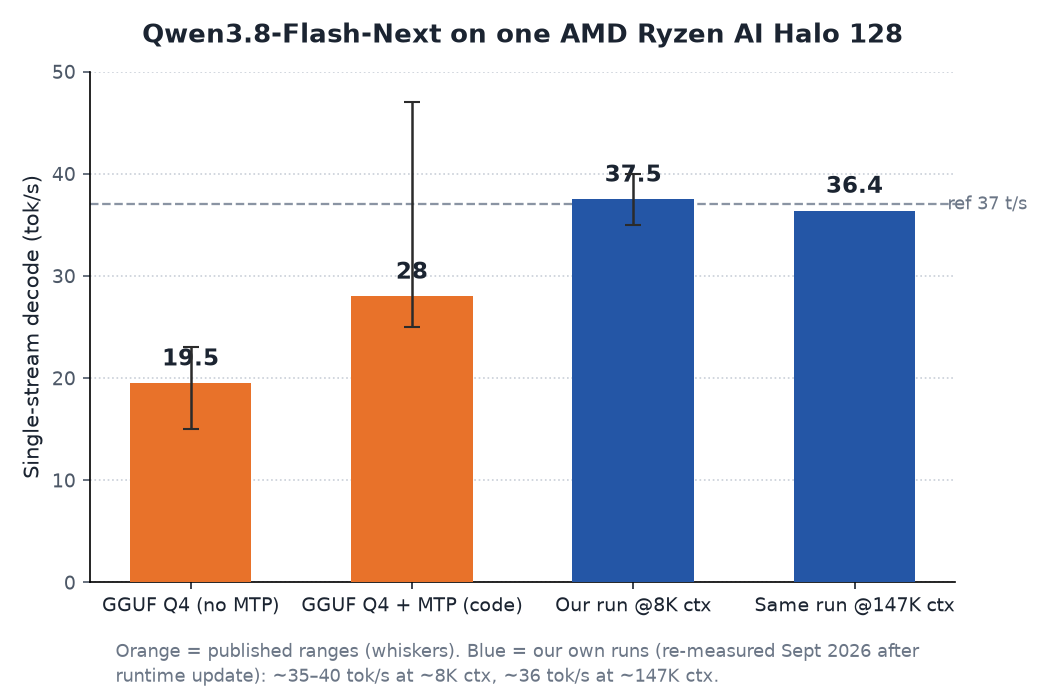
AMD Ryzen AI Halo 128 + Qwen3.8-Flash-Next

Decode speed chart for Qwen3.8-Flash-Next on one AMD Ryzen AI Halo 128: published GGUF Q4 ranges, plus our own re-measured runs after the Sept 2026 runtime update: ~35-40 tok/s at 8K context, ~36 tok/s at ~147K context
ConfigDecode
GGUF Q4, no MTP~16–23 tok/s
GGUF Q4 + MTP (code)~25–47 tok/s
Our own Halo coding-agent run, ~8K ctx (first-party)~35–40 tok/s
Same run at ~147K ctx (first-party)~36 tok/s

Native ~262K context. GGUF Q4-class on 128 GB unified memory. Best fit for the long-context coding agent on a single machine.

1B · Single Spark · decode

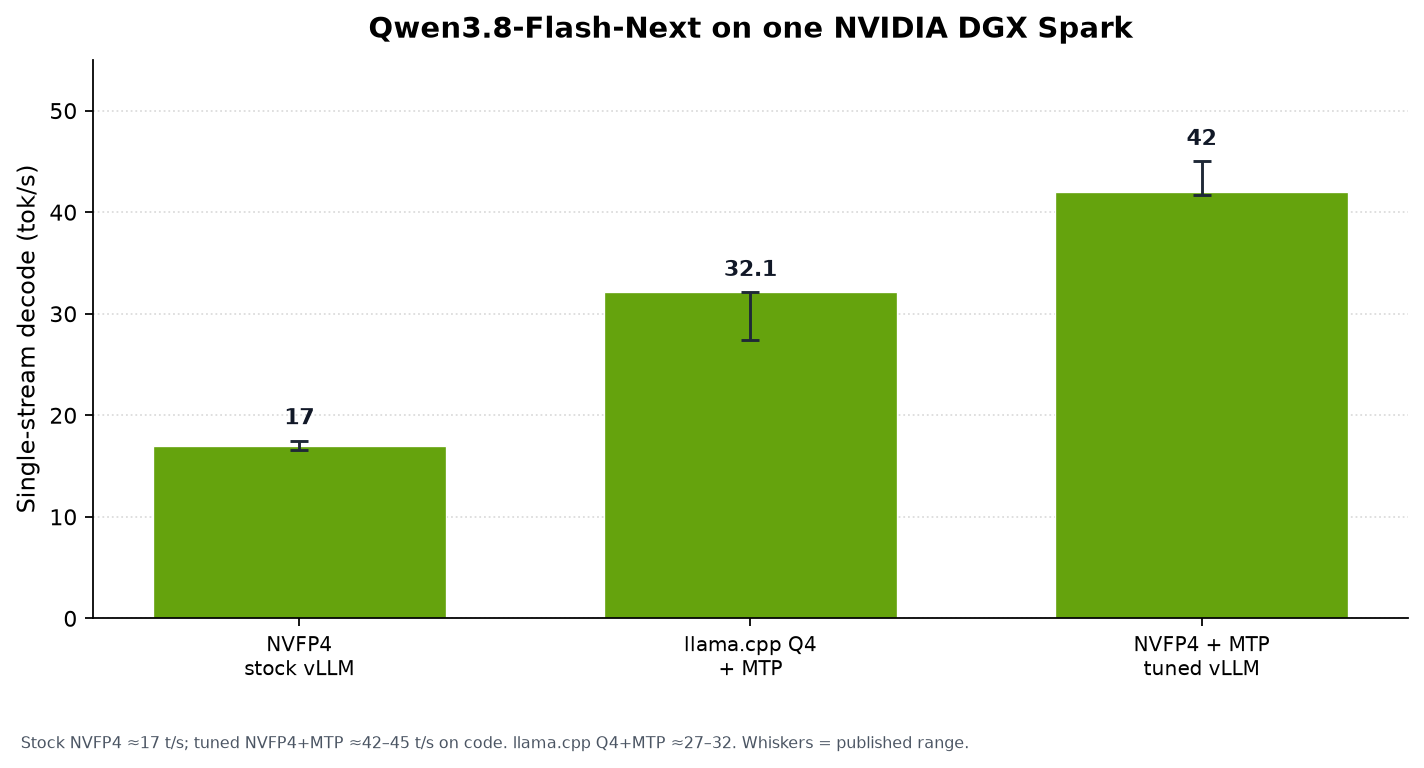
DGX Spark ×1 + Qwen3.8-Flash-Next

Decode speed chart for Qwen3.8-Flash-Next on one DGX Spark
ConfigDecode
NVFP4 stock vLLM~17 tok/s
llama.cpp Q4 + MTP~27–32 tok/s
NVFP4 + MTP tuned vLLM (code)~42–45 tok/s

Same model family on a single Spark only. Tuned NVFP4+MTP is the fastest on Spark; stock NVFP4 lands near Halo’s no-MTP band.

1C · Mac Studio · M3 Ultra (measured on 256/512 GB)

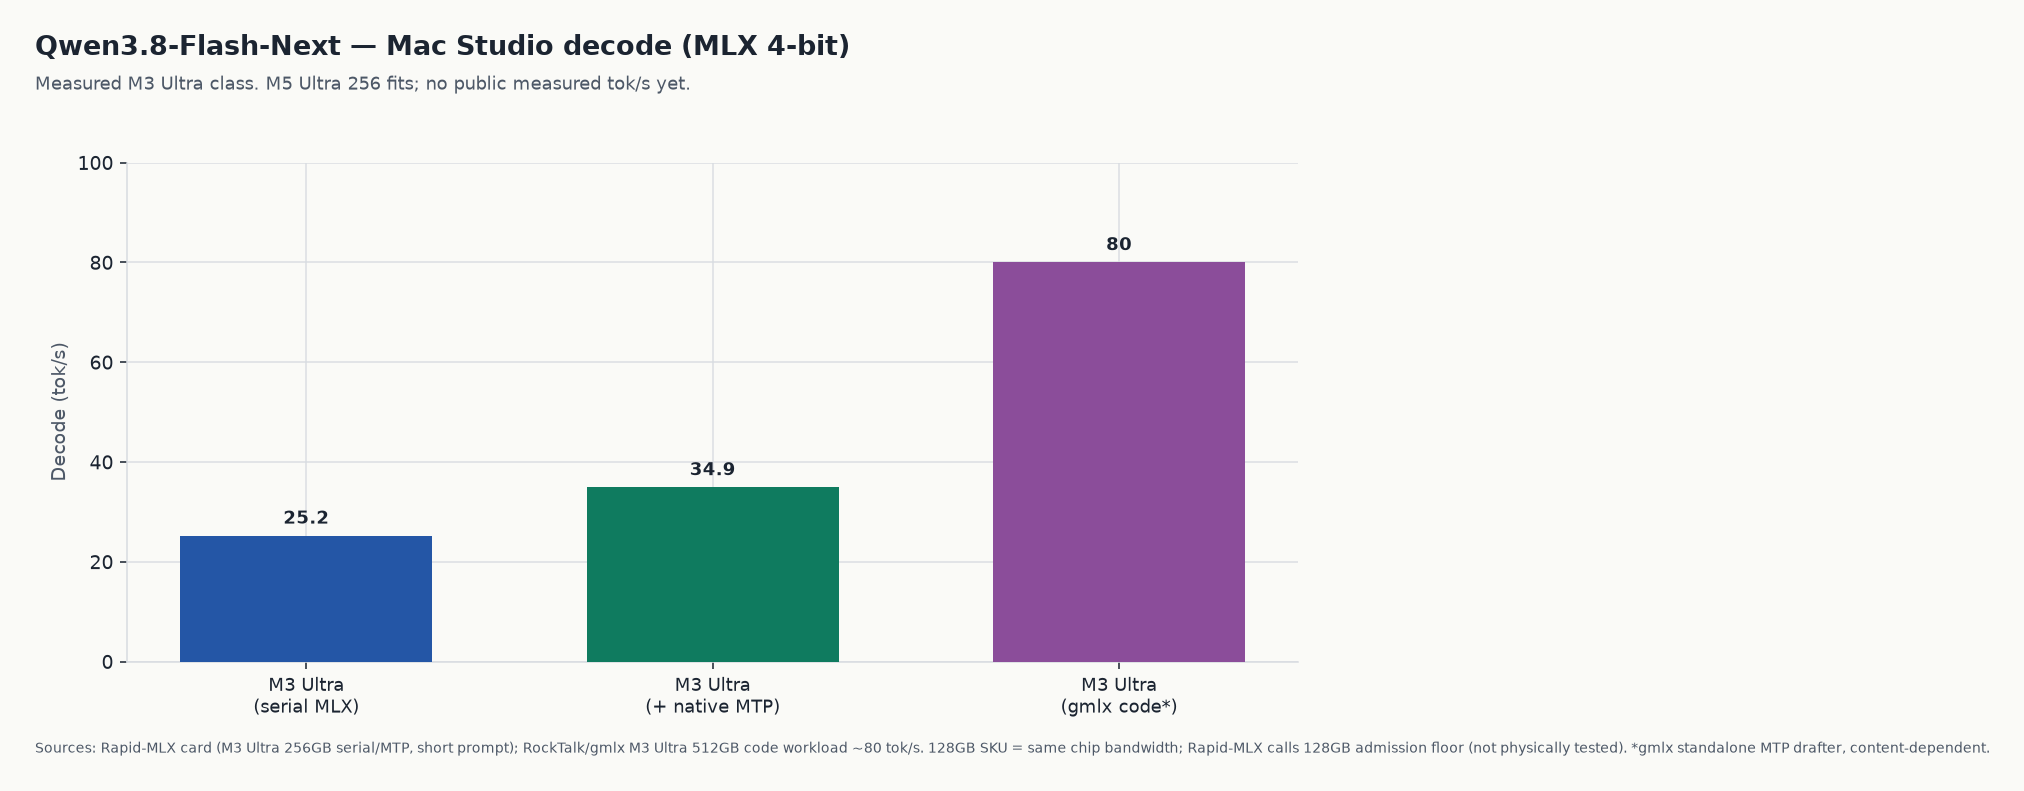
Apple M3 Ultra + Qwen3.8-Flash-Next (MLX)

Qwen3.8-Flash-Next decode on Mac Studio M3 Ultra with MLX serial, MTP, and gmlx code paths
ConfigDecode
MLX 4-bit serial (short prompt)~25 tok/s
MLX 4-bit + native MTP~29–35 tok/s
gmlx + MTP drafter (code)*~55–86 tok/s

Measured on M3 Ultra 256 GB (Rapid-MLX) and 512 GB(RockTalk/gmlx). The 128 GB SKU shares the same chip bandwidth; Rapid-MLX calls 128 GB an admission floor only (~100 GB weights) — not physically tested, expect tight context headroom. *gmlx content-dependent.

1D · Mac Studio · M5 Ultra 256 (not yet measured)

Apple M5 Ultra 256 GB + Qwen3.8-Flash-Next

ConfigDecode
MLX / Metal Q4 fitFits (~100 GB weights)
Public measured tok/sNone yet
Apple peak memory bandwidth (spec, not decode)1.2 TB/s

Capacity and bandwidth are public (256 GB @ 1.2 TB/s). Retail ships from Sep 22, 2026 (512 GB late October) — no reproducible public decode suite yet. Bandwidth is Apple's published peak, not a decode figure; community numbers are coming soon.

Quality · coding & agentic

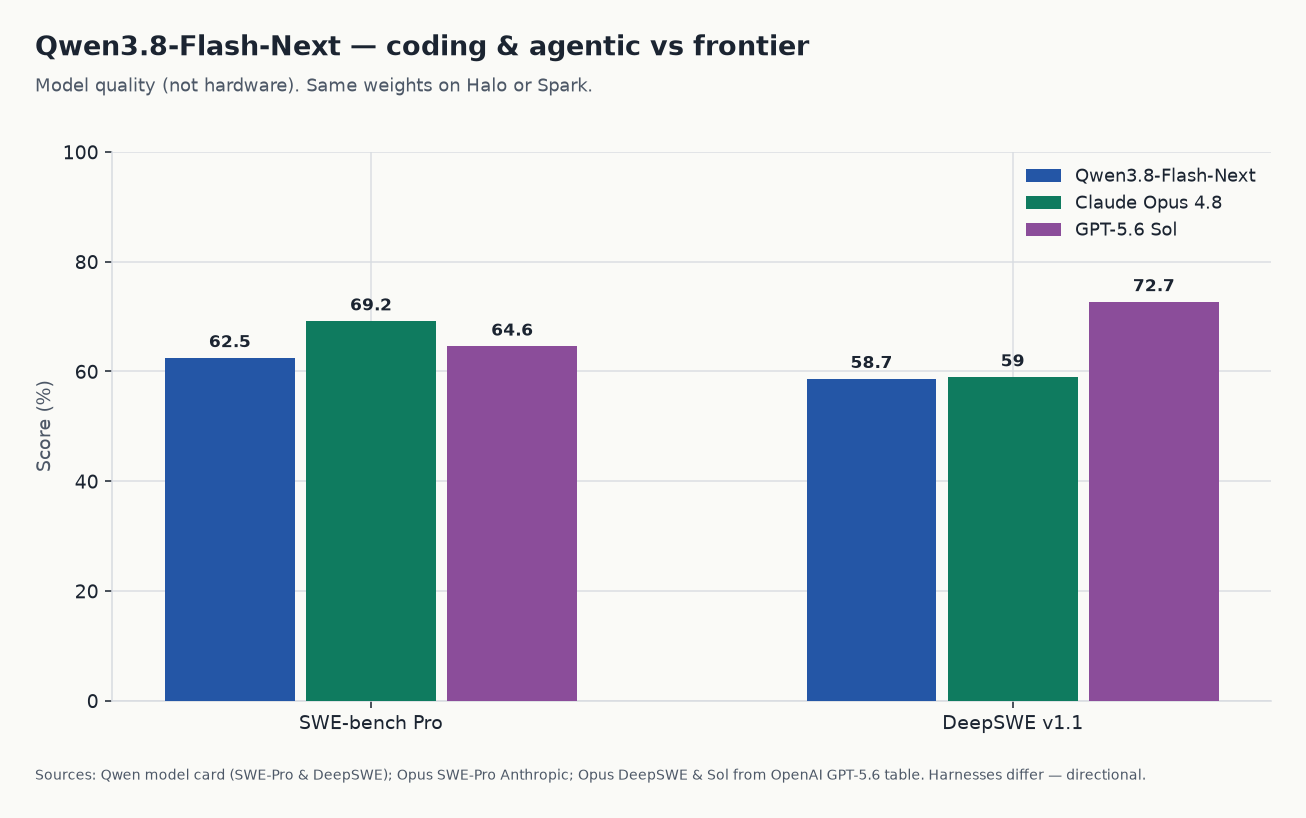
Qwen3.8-Flash-Next vs Opus 4.8 & GPT-5.6 Sol

Same weights whether you host on Halo, Spark, or Mac Studio. SWE-bench Pro is the harder coding bench; DeepSWE v1.1 is long-horizon agentic engineering.All scores below are vendor-published model-card / vendor-blog numbers, not our measurements.

SWE-bench Pro and DeepSWE scores for Qwen3.8-Flash-Next versus Claude Opus 4.8 and GPT-5.6 Sol
BenchmarkQwen3.8-Flash-NextOpus 4.8GPT-5.6 Sol
SWE-bench Pro62.5%69.2%64.6%
DeepSWE v1.158.7%59.0%72.7%

Section 2 · Two Sparks

Two Desktop Machine Clusters

Two-node DGX Spark (TP2) stacks is our current recommendation for these larger MoE models. Spark QSFP ConnectX-7 and a more mature TP2 stack greatly increase performance when clustered. Two Halos are possible via Thunderbolt, but the Shard Stack is not as mature as NVDA and not recommended for production speeds with larger models. Hopefully, a future stack will change that calculus. Mac Studio requires a minimum of 256GB RAM for these models. M5 Ultra 256 can host Q4-class weights, but there is no public measured decode suite yet. No public SWE-bench Pro is currently available, so quality uses DeepSWE + Terminal-Bench 2.1.

GLM-5.3-Flash · decode

On 2× Spark

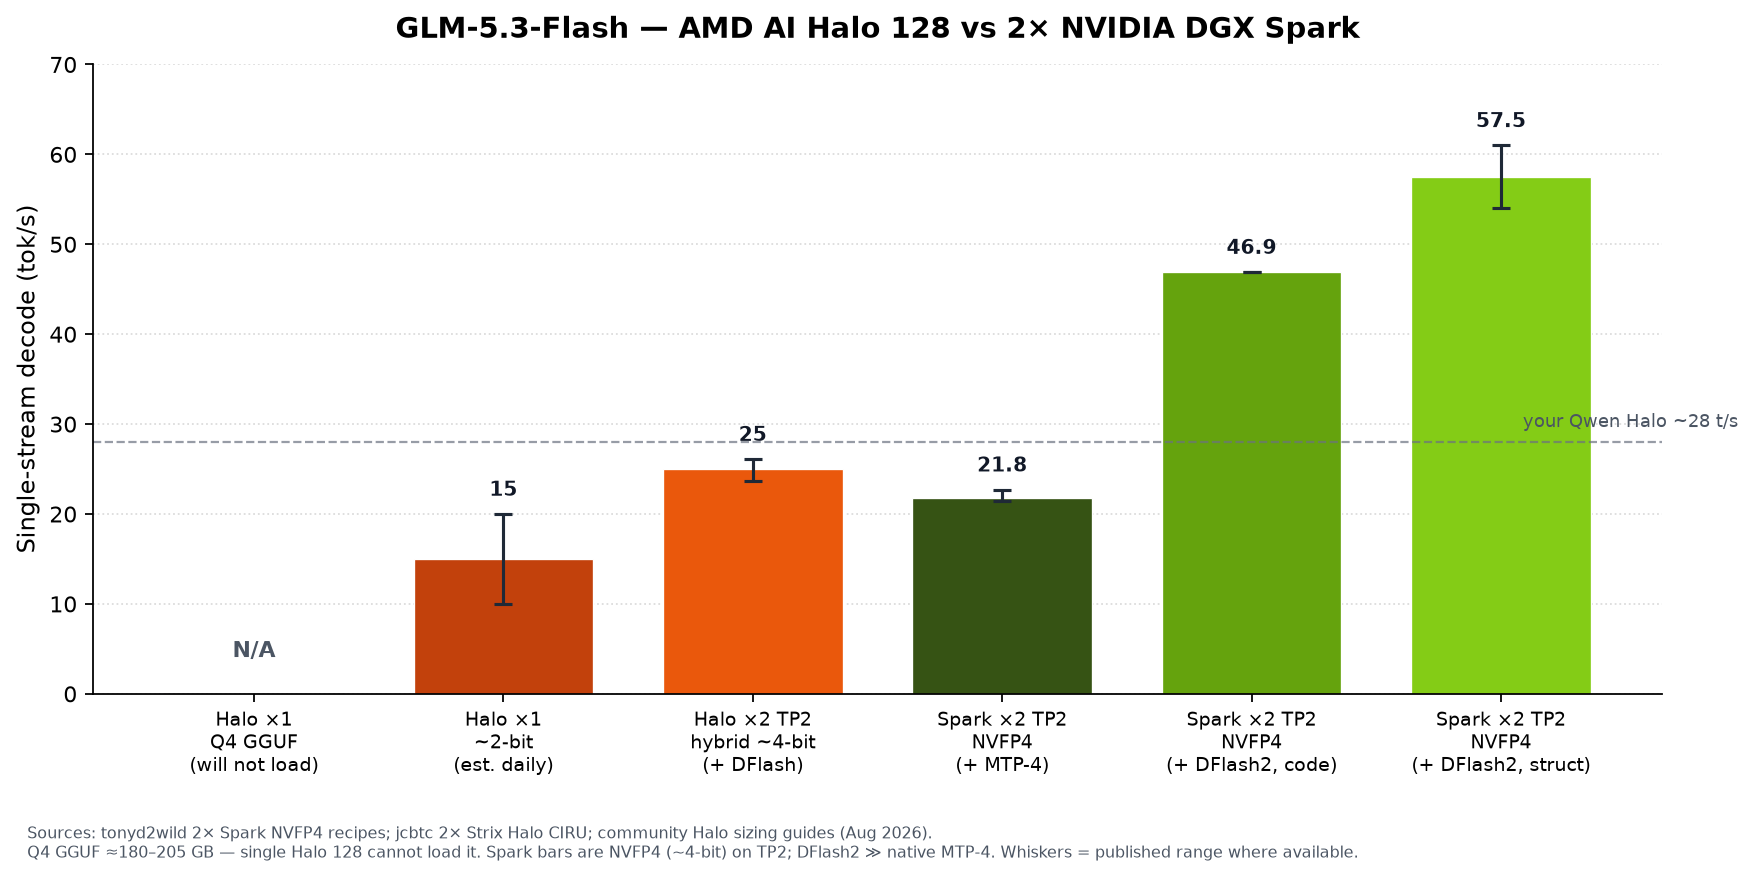
Decode speed chart for GLM-5.3-Flash on two DGX Sparks with Halo fit notes
ConfigDecode
Halo ×1 Q4Won’t load
Spark ×2 NVFP4 + MTP-4~22 tok/s
Spark ×2 NVFP4 + DFlash2 (code)~47 tok/s
Spark ×2 NVFP4 + DFlash2 (structured)~54–61 tok/s

Q4 GGUF ≈180–205 GB on one Halo. Practical path is 2× Spark + DFlash2. Mac: M3 Ultra 128 won’t host comfortably; M5 Ultra 256 can fit Q3/Q4 with headroom — no public measured tok/s yet.

DeepSeek-V4.1-Flash · decode

On 2× Spark

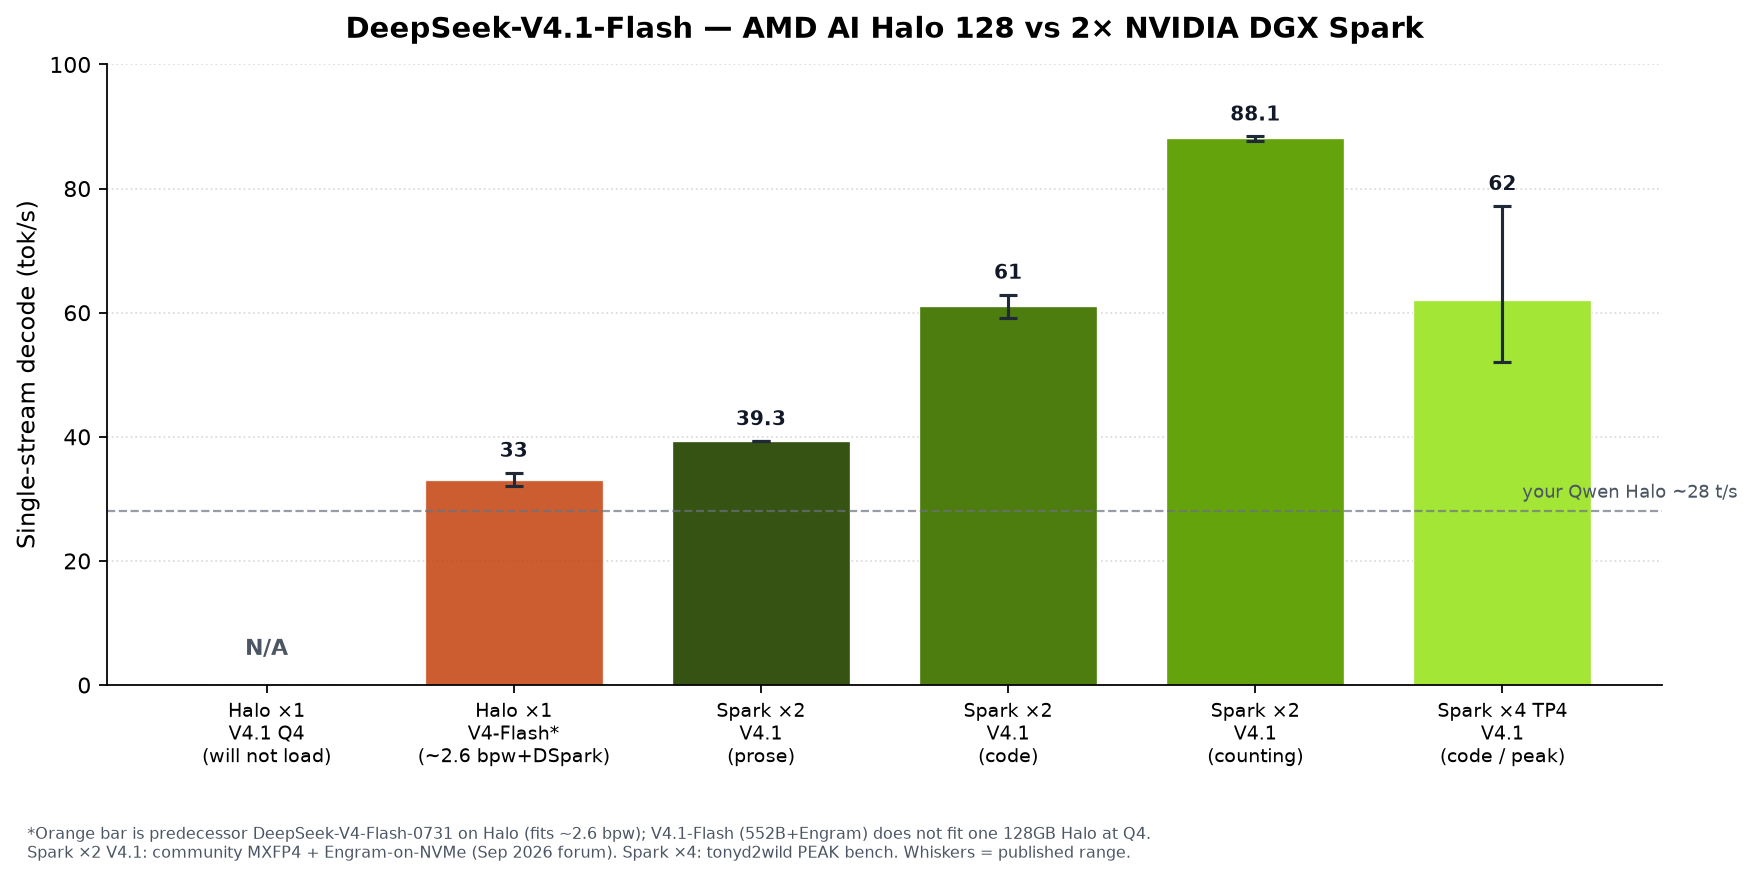
Decode speed chart for DeepSeek-V4.1-Flash on two DGX Sparks with Halo fit notes
ConfigDecode
Halo ×1 V4.1 Q4Won’t load
Halo ×1 V4-Flash* (prev gen)~32–34 tok/s
Spark ×2 V4.1 (prose)~39 tok/s
Spark ×2 V4.1 (code)~59–63 tok/s
Spark ×2 V4.1 (counting)~88 tok/s

*Predecessor V4-Flash-0731 fits one Halo. V4.1 needs 2× Spark (Engram on NVMe) or 4× for the best-documented stacks. Early MLX on M3 Ultra 256 with Engram on SSD reports only ~8.5–9.5 tok/s — experimental, not recommended for production. M5 Ultra 256 should fit; no public measured suite.

GLM · quality

vs Opus 4.8 & GPT-5.6 Sol

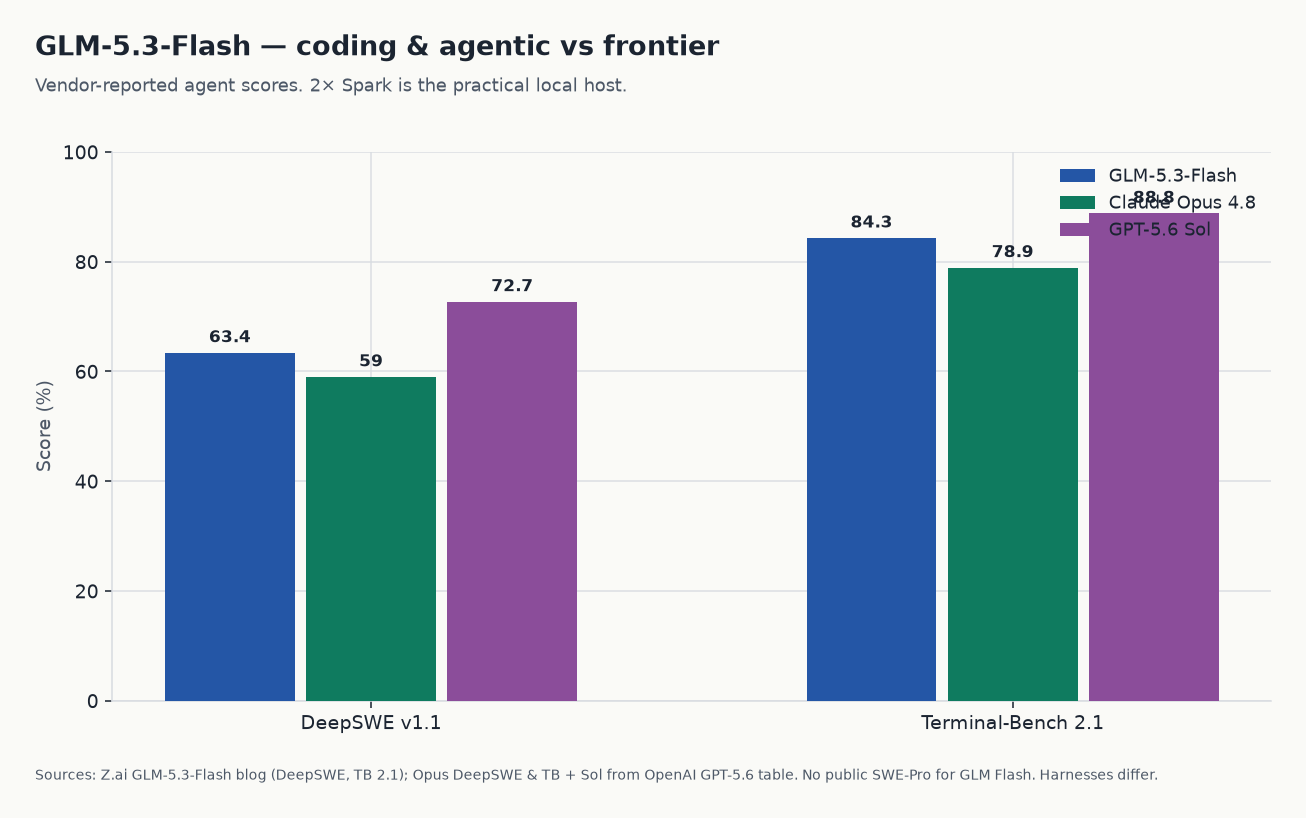
Vendor-published scores (Z.ai blog, OpenAI/Anthropic comparison tables) — not our measurements.

DeepSWE and Terminal-Bench scores for GLM-5.3-Flash versus Claude Opus 4.8 and GPT-5.6 Sol
BenchmarkGLM FlashOpus 4.8GPT-5.6 Sol
DeepSWE v1.163.4%59.0%72.7%
Terminal-Bench 2.184.3%78.9%88.8%

DeepSeek · quality

vs Opus 4.8 & GPT-5.6 Sol

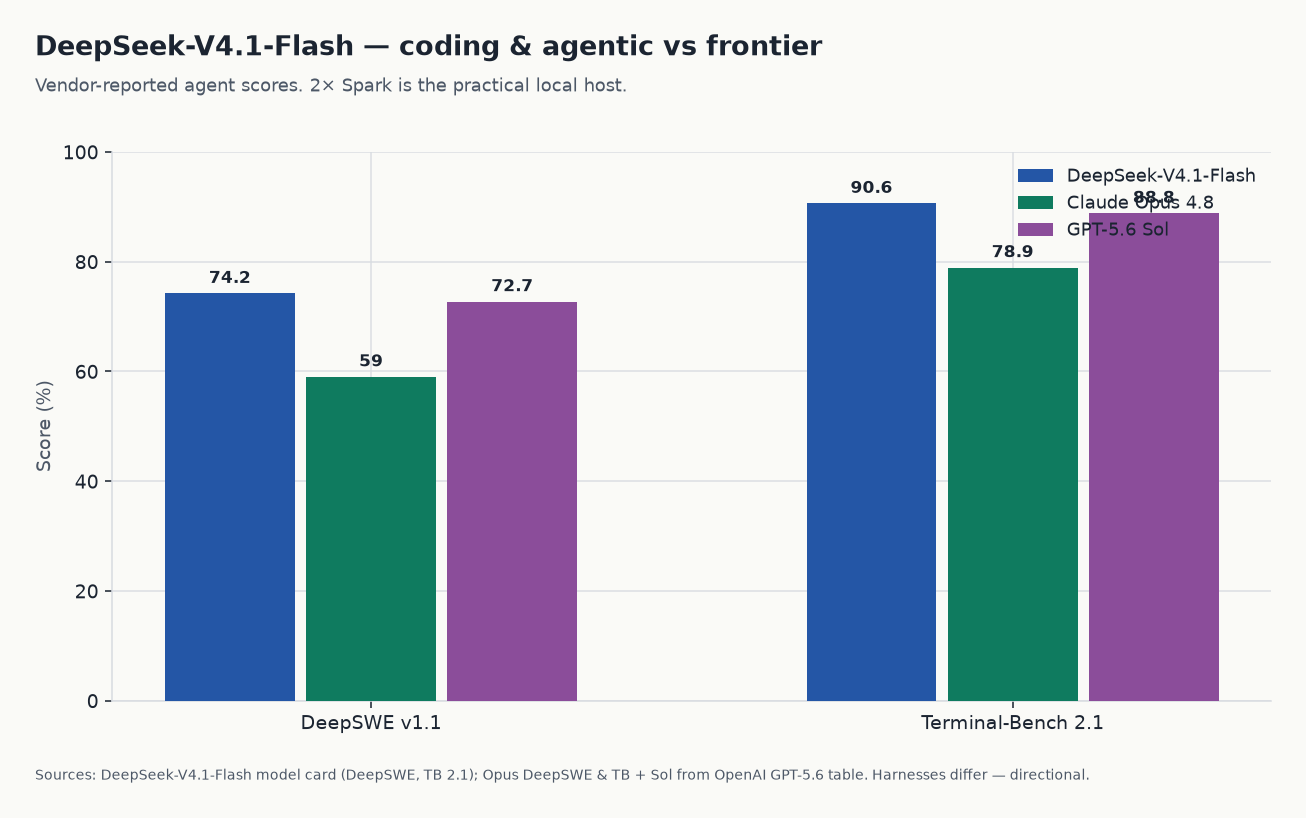
Vendor-published scores (DeepSeek model card, OpenAI/Anthropic comparison tables) — not our measurements.

DeepSWE and Terminal-Bench scores for DeepSeek-V4.1-Flash versus Claude Opus 4.8 and GPT-5.6 Sol
BenchmarkV4.1 FlashOpus 4.8GPT-5.6 Sol
DeepSWE v1.174.2%59.0%72.7%
Terminal-Bench 2.190.6%78.9%88.8%

Disclaimer

This page is Ratliff.io's current hardware and model advisory. It is not a warranty, a bid specification, or a hardware quote. Figures come from three different sources — vendor-published model cards and blogs, community forum benches, and Apple spec sheets — and each block states which. Except for the first row (our own Halo coding-agent run); nothing is measured by us and is in the public domain.

Numbers are directional only and current as of September 12, 2026. Configs, quants, runtimes, and prompts differ; results will vary on your hardware. Before any purchase recommendation for a client engagement, we re-measure on your kit.

Sources

Decode: community llama.cpp / vLLM / SGLang / Ember benches and NVIDIA DGX Spark forum recipes (Aug–Sep 2026). Mac Studio Qwen: Rapid-MLX M3 Ultra 256 GB card and RockTalk/gmlx M3 Ultra 512 GB notes (Aug–Sep 2026). M5 Ultra 256: fit from Apple memory/bandwidth specs — no public measured tok/s yet. Interconnect: NVIDIA DGX Spark user guide (ConnectX-7 QSFP, 200 Gb/s direct link) and AMD Ryzen AI Halo reviews/specs (single 10 GbE RJ-45). Configs, quants, and prompts differ.

Quality: Qwen3.8-Flash-Next model card (SWE-bench Pro, DeepSWE); Z.ai GLM-5.3-Flash blog (DeepSWE, Terminal-Bench 2.1); DeepSeek-V4.1-Flash model card (DeepSWE, Terminal-Bench 2.1); Claude Opus 4.8 SWE-bench Pro from Anthropic; Opus DeepSWE / Terminal-Bench and GPT-5.6 Sol figures from OpenAI’s GPT-5.6 comparison table. Agent harnesses are not identical — treat quality gaps as directional.